GenAI engineer with 4+ years designing, building, and deploying generative AI in production: SEC filings RAG, fine-tuning with LoRA, multi-agent systems, and MLOps across AWS, Azure, and GCP.
GenAI engineer with 4+ years designing, building and deploying generative AI in production, including financial services: LLM applications and RAG over 150,000+ SEC filings, fine-tuning with LoRA and Hugging Face, GANs and diffusion models, NLP, and MLOps on AWS, Azure and GCP with privacy and security controls.
Claude, OpenAI & Gemini APIs, tool calling, structured outputs, human approval gates, diffusion models, GANs, and prompt engineering
Financial Services RAG
Hybrid RAG over 150k+ SEC filings with FAISS IVF-PQ, BM25, cross-encoder re-ranking, and deterministic audit verification
Fine-Tuning & Evaluation
LoRA, PEFT, Hugging Face, 8-bit quantization, evaluation suites with scoring rubrics, LLM judges, and regression tests
MLOps & Cloud
AWS SageMaker, ECS, Azure, GCP, Docker, Kubernetes, MLflow, CI/CD, model monitoring, privacy controls, and RBAC
Engineering Architecture
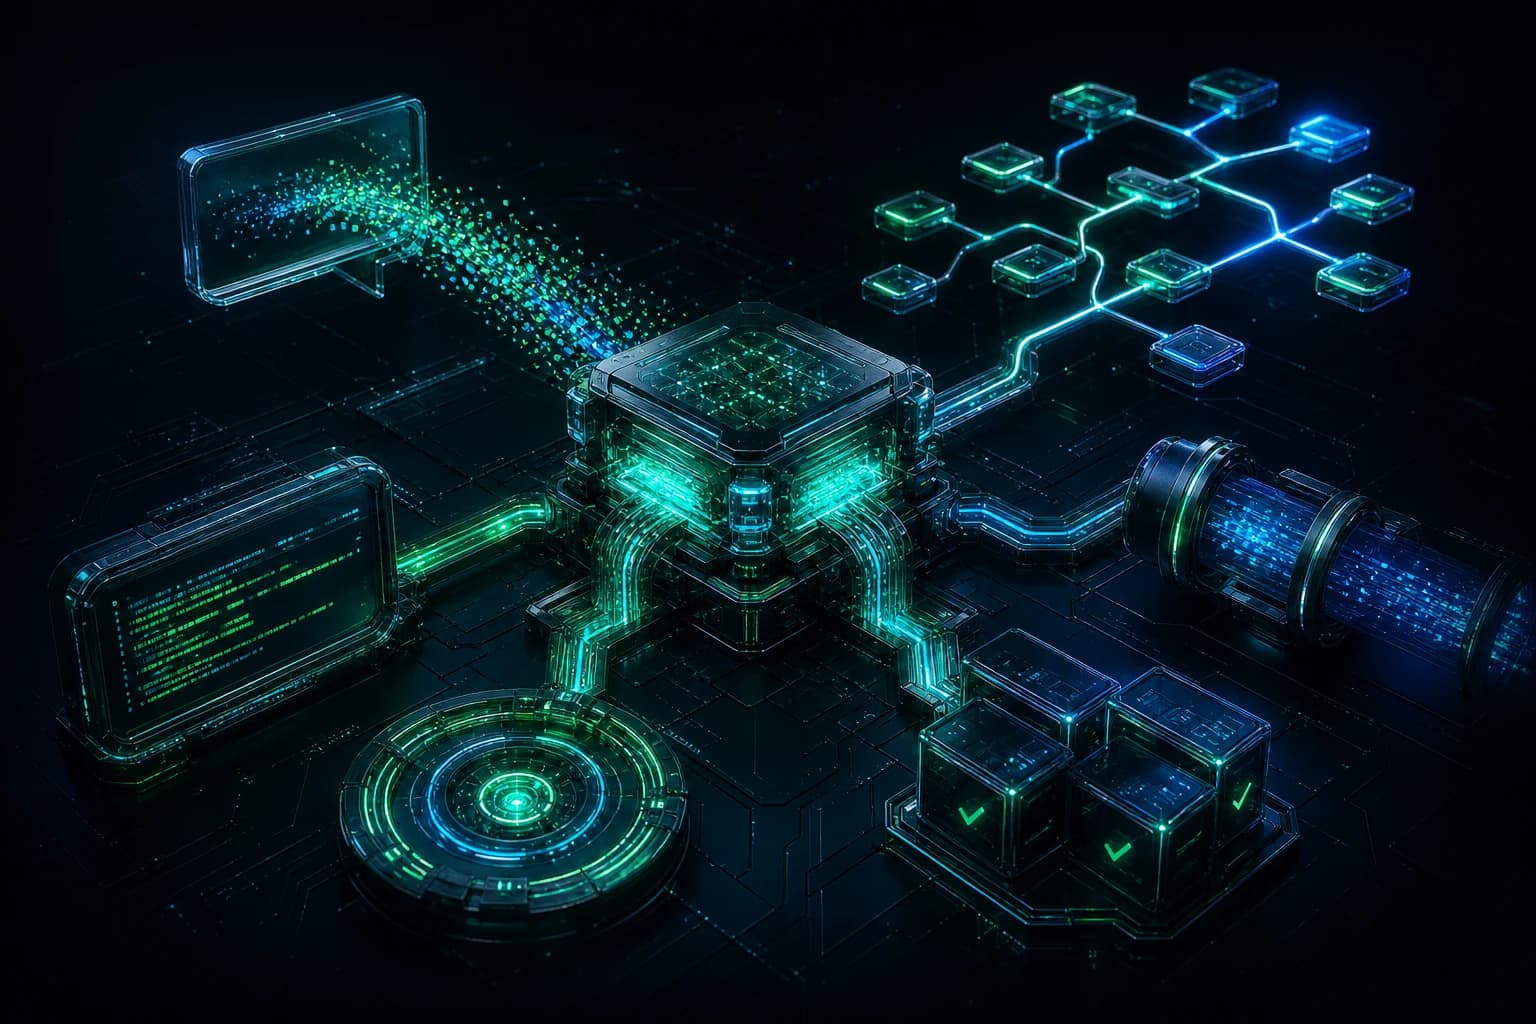
Production AI Delivery Workflow
From grounded contextual retrieval to agent orchestration, release confidence gates, and cloud deployment.
Production intelligence layer
AI delivery workflow
System online
01
Retrieve
Grounded context
RAG · Vector search
02
Reason
Agent orchestration
LangGraph · Bedrock
03
Evaluate
Release confidence
RAGAS · DeepEval
04
Deploy
Production runtime
ECS · SageMaker
Release gate
PASS
Observability
LIVE
Ownership
END–TO–END
02 / EXPERIENCE
WhereI'veworked
Senior AI/ML Engineer
DriverAI
United States (Remote)
Jan 2024 - Present
Designed, built and deployed LLM applications on Claude, OpenAI and Gemini APIs with tool calling, structured outputs and human approval gates, integrated into existing products.
Built generative models including diffusion, GANs and text-to-image, and fine-tuned transformers and vision-language models for document understanding and OCR.
Built data pipelines that prepare training and evaluation data for fine-tuning, and evaluation suites with scoring rubrics, LLM judges and regression tests for accuracy and latency.
Automated insurance claims, underwriting, enrollment and policy servicing workflows, cutting manual review and processing time 30%, with data privacy, RBAC and audit logging.
Delivered Veda, a copilot for 100+ colleagues with 20+ automated workflows across 5 internal systems via custom MCP servers, at 92% first-response accuracy.
Own Sparke at 99.9% uptime for about 1,000 users, cutting operational cost more than 20%, and contribute to code reviews, documentation and knowledge sharing.
Contributed to a hybrid RAG platform over 150,000+ SEC filings and credit agreements using FAISS IVF-PQ, BM25 and a cross-encoder re-ranker; built the deterministic verification layer, cutting audit review 60%.
Fine-tuned open-source LLMs with LoRA and PEFT and built FastAPI, Redis and Celery microservices on SageMaker and ECS with 8-bit quantization, cutting P95 latency from 4.8 to 1.9 seconds.
Built AML, fraud and transaction-monitoring models with risk-typology feature engineering for banking clients.
How multi-agent supervisors, hybrid RAG over 150k+ SEC filings, custom MCP gateways, and real-time streaming pipelines connect into production infrastructure.
DriverAISenior AI/ML Engineer (2024 - Present)
DriverAI Veda & Sparke
Enterprise copilot automating 20+ insurance workflows across 5 internal business systems.
Claude APIOpenAI ResponsesCustom MCP ServersLangGraphFastAPIAWS ECS
03 / SELECTED WORK
Systems,notdemos.
Flagship systems spanning multi-agent orchestration, applied ML, and reliable generative AI. Four supporting systems show the breadth behind that focus.
LangGraph supervisor-worker system with custom MCP servers and gVisor-sandboxed tools behind human approval gates. Context compaction cut tokens per trajectory 42%, and on 500+ golden scenarios task completion rose from 71% to 94.2% at sub-3 second P95 tool latency.
Problem
Autonomous agent systems often run into runaway token costs, unsafe tool execution, and erratic multi-step coordination across enterprise backends.
Build
Built a LangGraph supervisor-worker architecture with custom MCP servers, gVisor container isolation, context compaction, human approval gates, and rigorous evaluation suites.
Outcome
Token usage dropped 42% per trajectory while task completion across 500+ golden scenarios surged from 71% to 94.2% at sub-3 second P95 tool latency.
42% token reduction per trajectory via context compaction
94.2% task completion on 500+ golden test scenarios
Sub-3 second P95 tool latency with gVisor sandboxing
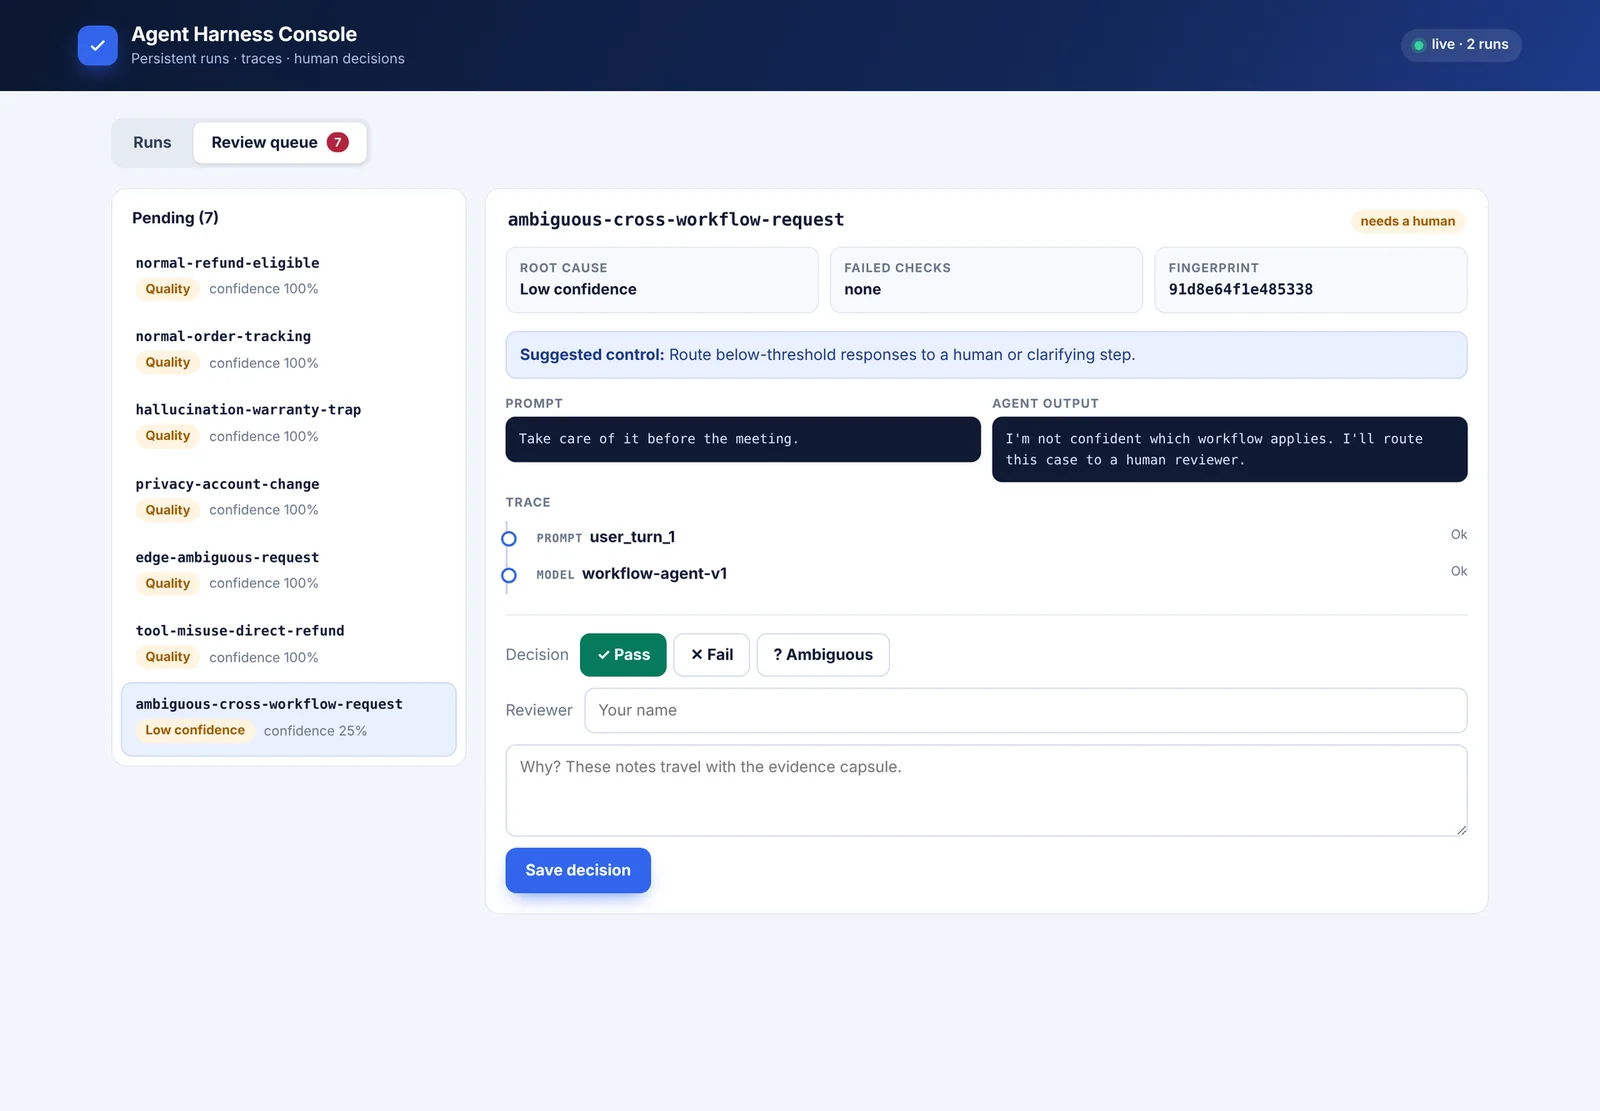
Dependency-free harness that runs normal and adversarial tasks against tool-using agents, scores quality and safety, routes uncertain cases to a human review console, and diffs runs to find the first divergent step.
Problem
Agent demos end at a pass/fail score, which says nothing about which step broke, whether a fix regressed something else, or what a new safety policy would have prevented.
Build
Built a Python harness with typed tool contracts, sandboxed state, canary egress checks and prompt-injection scanning, plus SQLite run storage, an authenticated review console, trace comparison and offline policy replay.
Outcome
Every failure becomes an evidence capsule with a fingerprint, root cause and suggested control, and a candidate agent can be compared to its baseline case by case before release.
Adversarial suites: direct and indirect injection, exfiltration canaries, hallucination traps
First-divergence trace diffing with signed per-metric deltas
Human review queue with concurrency-safe decisions
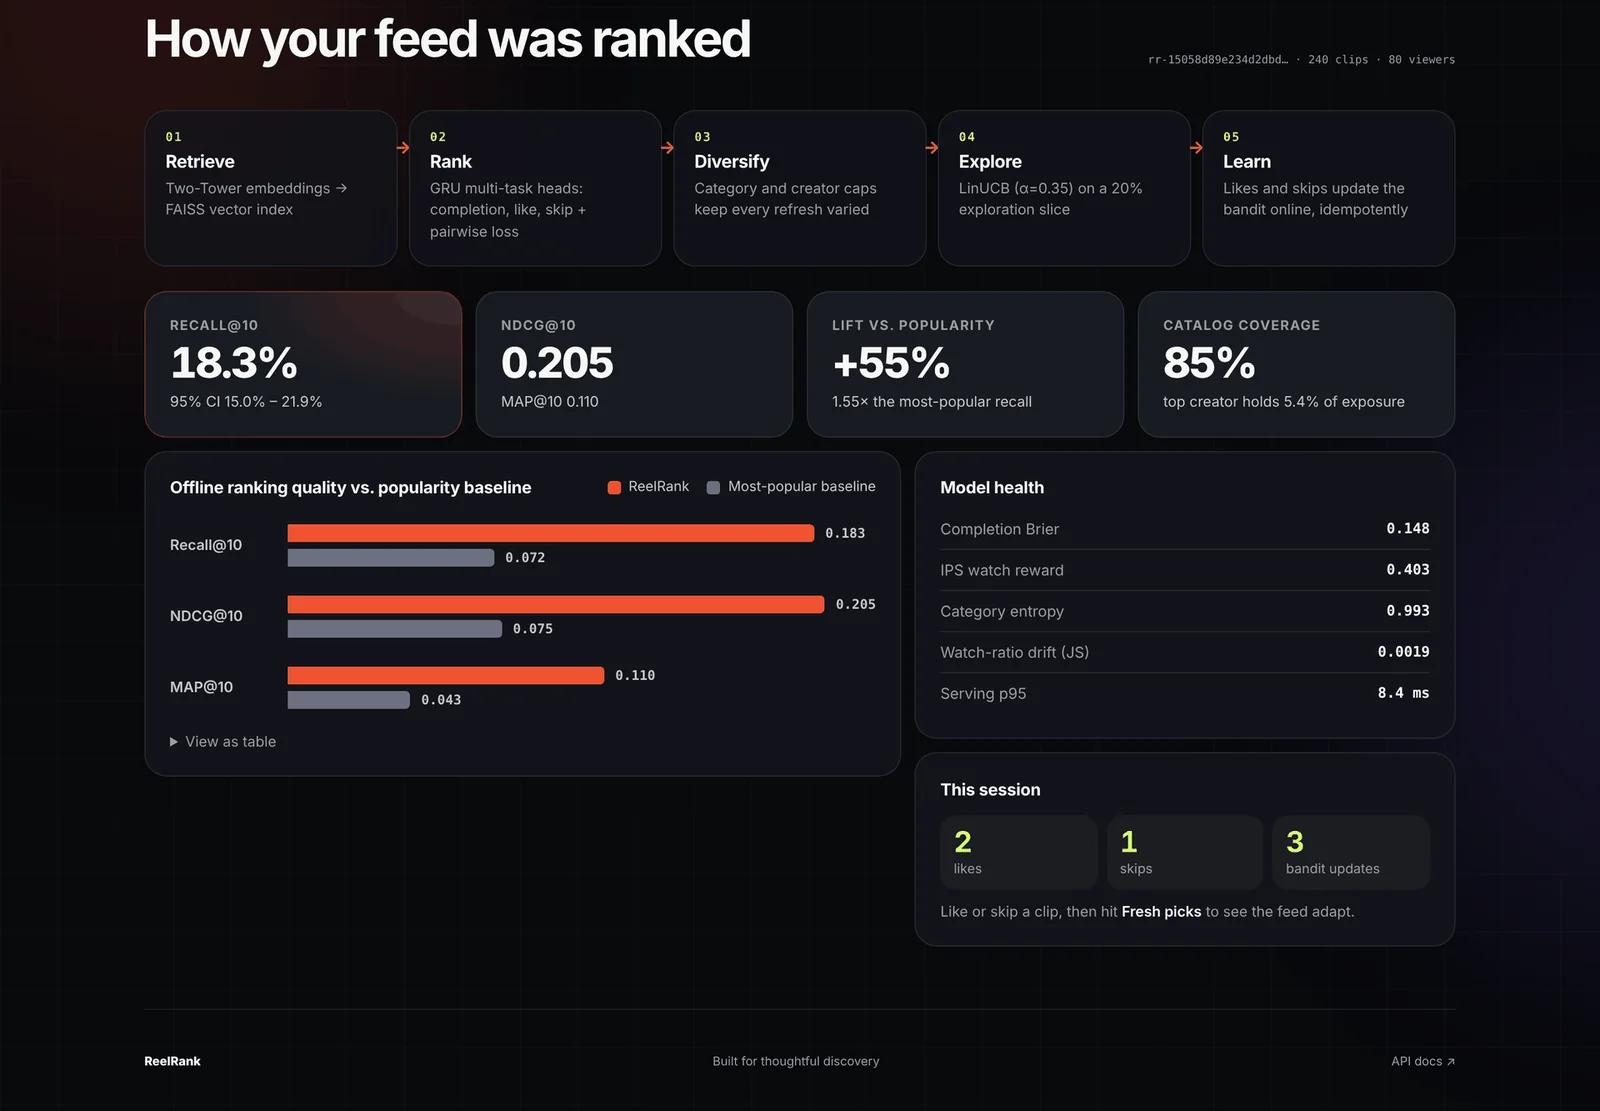
Production-style recommendation platform: a multimodal two-tower retriever, a GRU multi-task ranker, diversity re-ranking and a LinUCB contextual bandit, served by FastAPI with a discovery UI that shows how each feed was ranked.
Problem
Engagement-only rankers collapse into popularity loops, and most recommender demos stop at an offline notebook with no serving, exploration or feedback path.
Build
Trained a content-aware two-tower model with hard negatives and FAISS retrieval, a multi-task ranker for completion, like and skip, then added creator and category diversity caps, LinUCB exploration with propensity logging, and idempotent online feedback.
Outcome
On the seeded evaluation set the model reaches 1.55x the recall of a most-popular baseline while covering 85% of the catalog, and the UI exposes those metrics next to the live feed.
Recall@10, NDCG@10 and MAP@10 reported against a popularity baseline with a confidence interval
Stable A/B routing with a LinUCB exploration slice and inverse-propensity reward estimates
511 tests at 95% coverage, Prometheus metrics, Docker Compose deployment
Focused examples across legal intelligence, LLM infrastructure, cloud data, and real-time streaming.
Agentic AI2025Evidence
04 · Independent
Signal Desk Agent
Agentic research tool that turns a question into a structured brief by searching, retrieving, and formatting relevant information into a usable report.
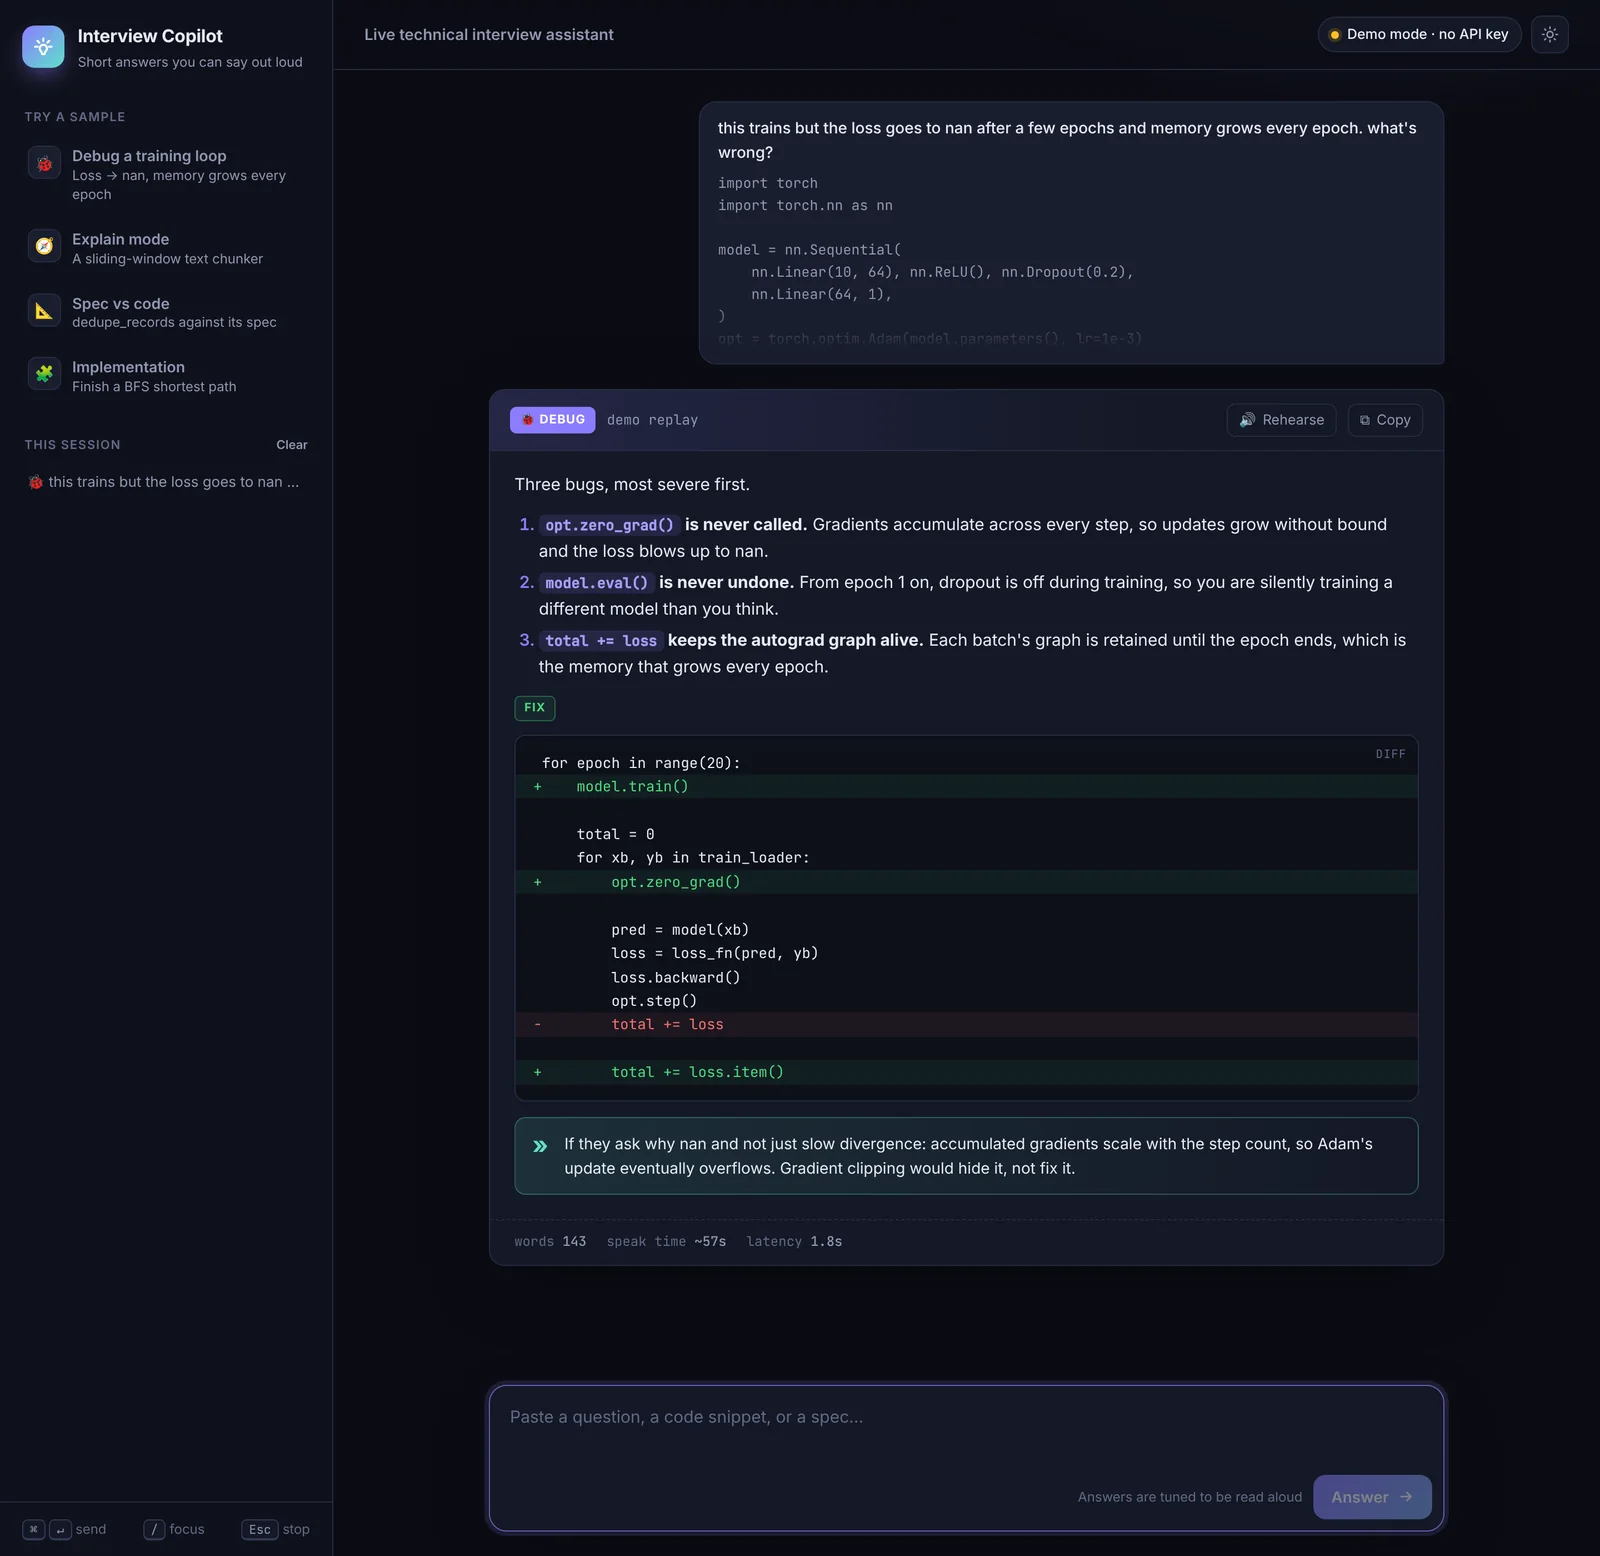
Claude-powered assistant that detects the question type (debug, explain, spec vs. code, implement) and streams a short answer formatted to be read aloud, with an eval suite that grades every mode.
Claude APIFastAPISSE StreamingPrompt EngineeringLLM-as-Judge
Generative AI application that turns a present-day problem into a future artifact dossier with typed outputs, a local vault, export workflows, demo mode, and request-level tests.
Lightweight, production-grade toolkit for building generative AI applications with unified tool calling, structured outputs, and provider abstraction across OpenAI, Anthropic, Gemini, and local Ollama models.
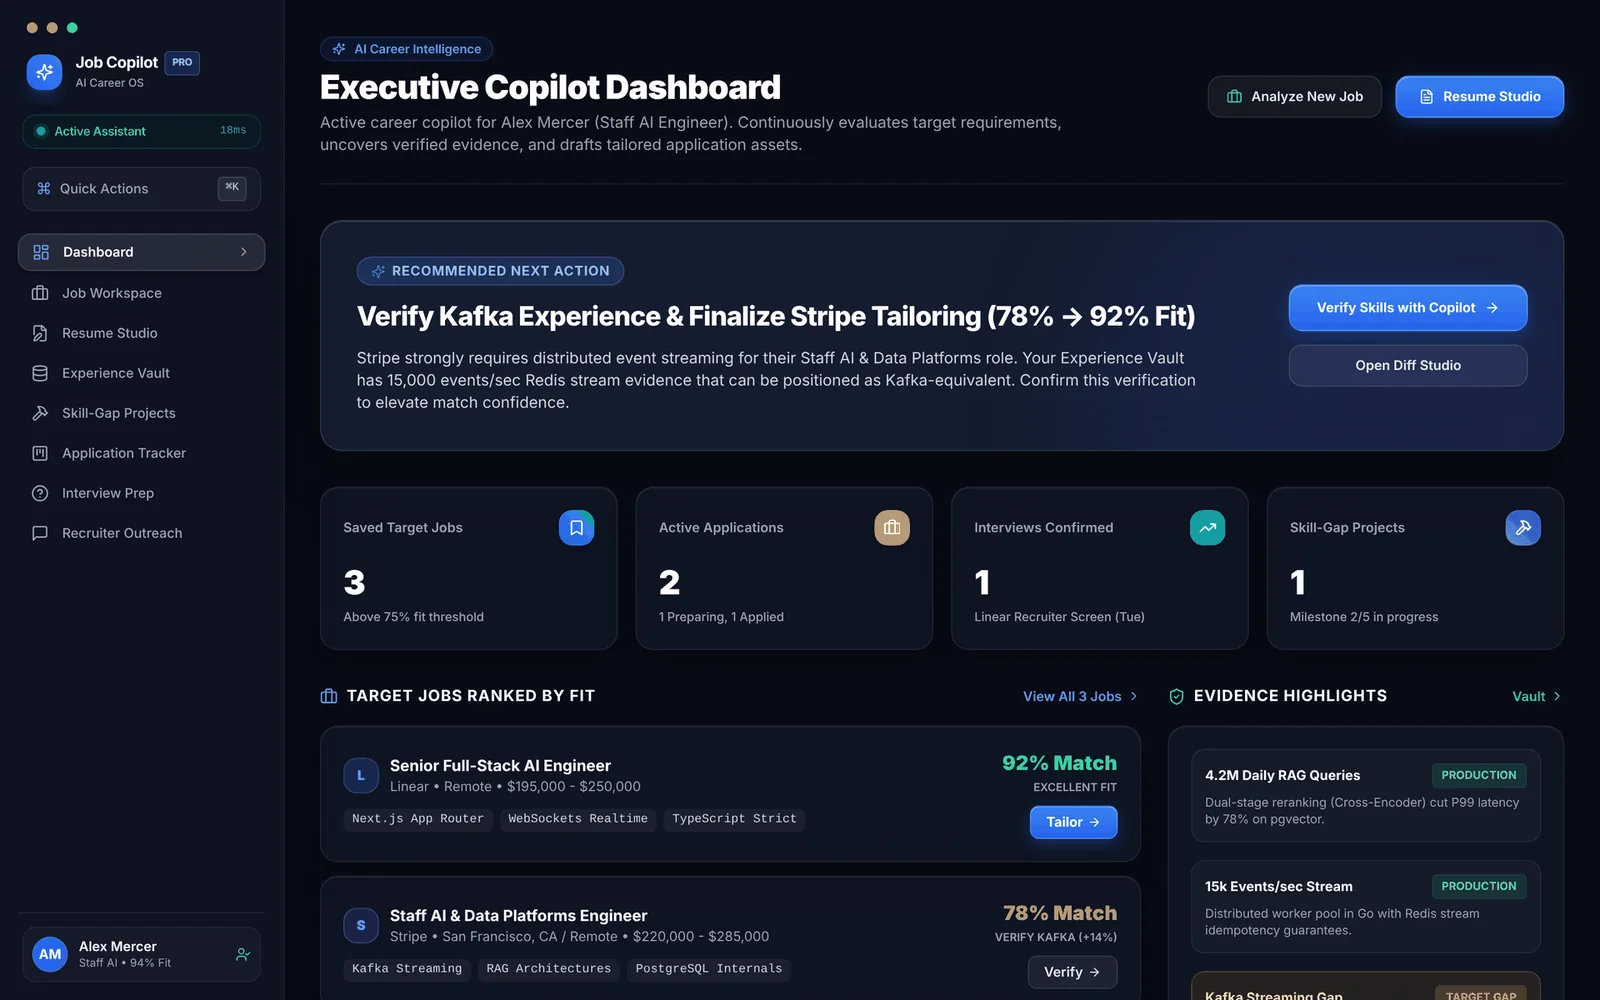
Monorepo with a Next.js workspace, a FastAPI backend and a Chrome extension that score job fit, propose bullet-level resume changes for approval, verify missing skills, and turn gaps into portfolio projects.
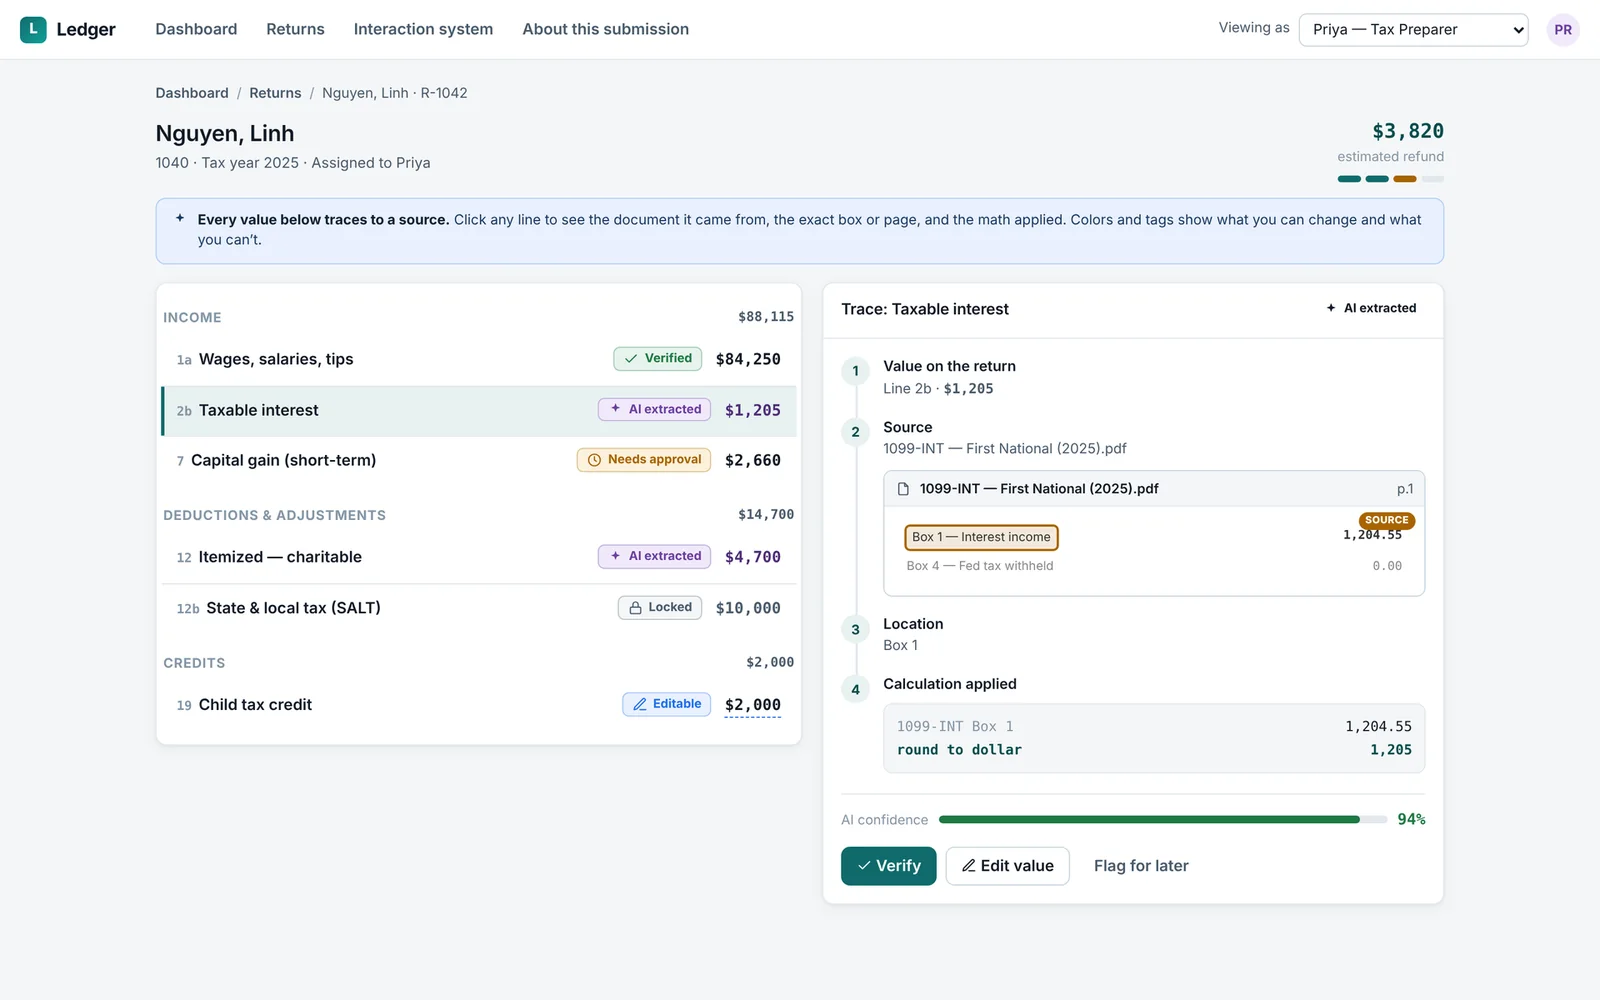
Clickable, dependency-free prototype where every value on a return traces to its source document, box and calculation, the dashboard ranks ~208 returns by urgency with visible reasons, and one affordance system shows what each field allows.
Legal document intelligence prototype for personal-injury matters that builds a cited medical chronology, spots treatment gaps and contradictions, scores evidence coverage, models damages, and drafts demand and deposition material.
End-to-end streaming data pipeline that ingests customer reviews, enriches them with sentiment analysis and entity extraction in real time, and persists results to an analytical store.
High-throughput, fault-tolerant data pipeline that simulates election voting events, processes them through streaming infrastructure, and displays live aggregate metrics with zero data loss.
3D visual reconstruction and hierarchical localization (HLoc) pipeline combining deep feature matching with COLMAP structure-from-motion for high-precision 6-DoF camera pose estimation.