Interview Copilot
Speakable answers for live technical interviews, held to a written spec
Claude-powered assistant that detects the question type (debug, explain, spec vs. code, implement) and streams a short answer formatted to be read aloud, with an eval suite that grades every mode.
Visual evidence
Spec vs. code mode
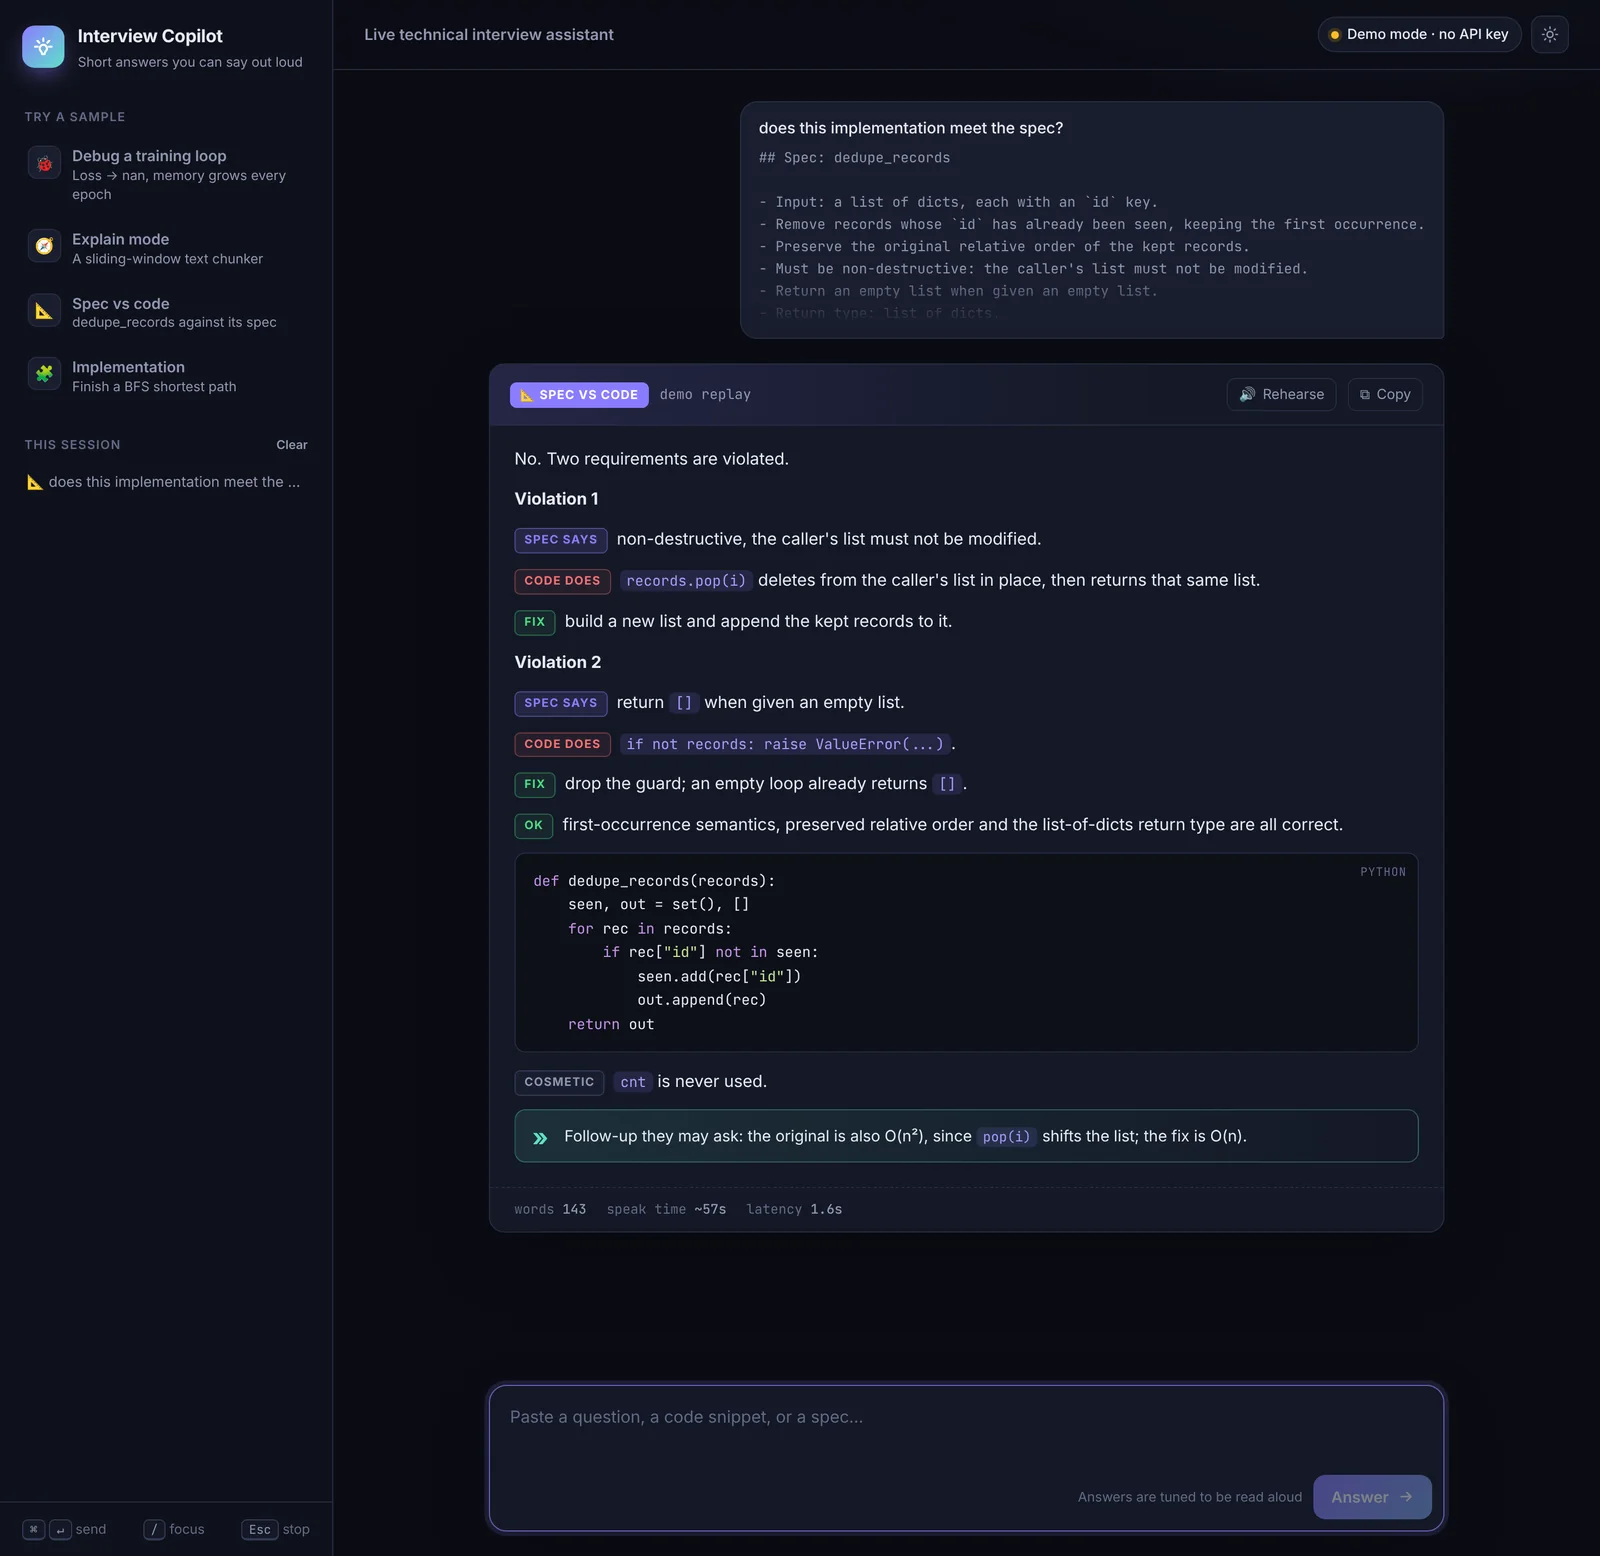
Supplementary evidence
Home and sample questions
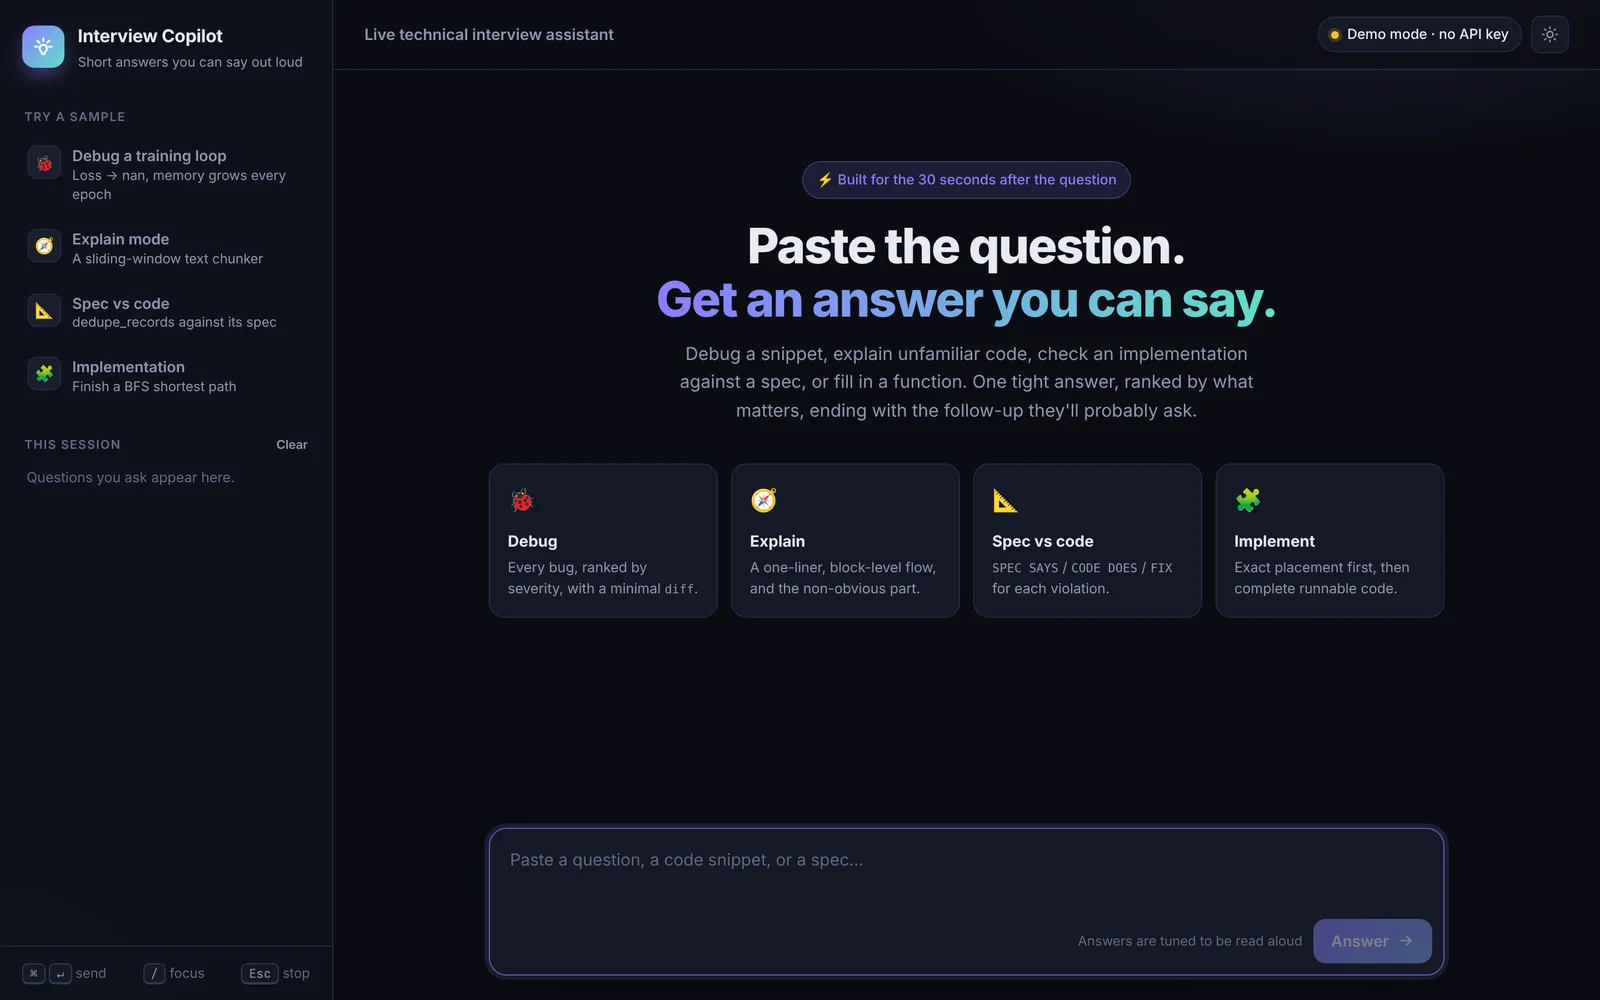
Case study
Problem, Build, Outcome
Problem
General chat assistants answer interview questions with tutorials, so the useful part is buried and the answer takes too long to say.
Build
Wrote a mode-based system prompt with strict output formats, a FastAPI server that streams Claude responses over SSE with prompt caching, and a dependency-free UI with mode detection, a rehearse-aloud button and speak-time estimates.
Outcome
Each answer leads with the result, ranks issues by severity and ends with the likely follow-up; deterministic checks plus an LLM judge keep the prompt honest as it changes.
Architecture
System Flow
Architecture Notes
- The system prompt lives in PROMPT.md and is loaded at startup, so the document is the source of truth.
- Server-sent events stream meta, delta, done and error frames to the browser.
- The eval runner combines format checks with a structured-output judge.
Engineering choices
Technical Decisions
Used low-effort adaptive thinking because latency matters more than depth during a live interview.
Cached the system prompt so follow-up questions in a session are cheaper and faster.
Rendered answer labels (FIX, SPEC SAYS, PLACEMENT) as visual tags so they can be scanned mid-conversation.
Evidence
Proof Points
Four answer modes, each mapped to explicit pass/fail criteria
Structural checks run in CI; an LLM judge grades content against the rubric
Demo mode works without an API key
Next read